Links

pmuellr is Patrick Mueller

other pmuellr thangs: home page, twitter, flickr, github

Tuesday, January 22, 2019

reboot

After 3.5 years at NodeSource, I retired at the end of last week. I really loved working there - great people, fun products, challenging problems to solve. Alas, my work history shows that I tend to not stick around an organization more than 3-4 years, even with great projects. I kinda enjoy mixing things up every few years, and as I get older ... there realistically won't be that many more for me, before I really retire.

So, shakin' things up!

Taking a few months off, but here's my current rough list of TODOs:

In order to kill more birds with less stones, there's a particular app I'd like to build to display weather information, something I've been wanting to build for a while. So I guess I can try building that with the client bits, deploying that a bunch of different ways, and blog about it. A Max standalone app for it is a stretch goal :-)

Sunday, September 10, 2017

moar profiling!

I'm a long-time fan of using CPU profilers to analyze programs.

CPU profilers are great because they provide insight into our programs that you can't get easily any other way - how fast - or more likely how slow - are functions in your code. I've learned with profilers that there's no point in guessing what code you think is fast or slow, because:

  • you're likely wrong, or will find surprises
  • it's so easy to profile some code, just do it!

For Node.js, there are some useful profilers available:

Of course I'm partial to N|Solid since I work on it, <wink/>.

And yet ... I've grown a little restless with our current crop of profiling tools.

The defacto visualization for profiles is flame graphs. But I have issues:

  • the interesting dimension to be looking for is the widths of the boxes, but my eye is often drawn to the heights

  • they don't provide much room for textual information, since many of the boxes can be very thin

  • usually, all I care about looking at a profile are the most expensive functions, but visually sorting box widths across a 2 dimensional graph of boxes doesn't make a lot of sense

The age-old profile visualization is the table/tree, where functions are displayed as rows in a table, but can be expanded to show the callers or callees of the individual functions. While a grand idea - merging tables and trees into a single UI widget - it's also as tedious as you can imagine it might be. Lots of clicking to expand/contract the tree bits, and then the whole thing gets very noisy.

Both of these tools are sufficient, and do provide a lot of value, but ... I feel like we can do better.

And so I've started playing with some new tooling:

  • moar-profiler - a command-line tool to generate profiles for Node.js processes, that adds even moar information to the profile than what v8 provides (eg, source, package info, process meta data). These profiles are compatible with every v8 .cpuprofile digesting tool, they just extend the data provided in the "standard" profile data.

  • moar-profile-viewer - a web app to view v8 .cpuprofile files generated from Node.js profiling tools, that provides even moar goodies when displaying profiles generated from moar-profiler

Here's what the profile viewer looks like with a profile loaded:

moar profile viewer

The viewer is at Minimum Viable Product state. There are no graphs. There are no call stacks. There are only lists of functions, and the ability to get more information on those functions - callers and callees - and a view of the source code of the function. Gotta start somewhere!

Some of the fun stuff the profile viewer does have is:

  • displaying the package and version a function came from, along with a link to the package info at npmjs.org

  • annotated source code

  • ability to toggle hiding "system" functions vs "user" functions

Generating a profile with moar-profiler is pretty easy:

  • run your program with the --inspect option (requires Node.js >= version 6):
node --inspect myProgram.js arg1 arg2 ...
  • in a separate terminal, run moar-profiler which will generate the profile to stdout
moar-profiler --duration 5 9229 > myProgram.cpuprofile

In this case, a 5 second profile will be collected, by connecting to the Node.js process using the inspect port 9229 (the default inspect port).

Now that you have a .cpuprofile file, head over to the moar profile viewer web app, and load the file (or drop it on the page).

If you would like to test drive the web app without generating a .cpuprofile file first, you can download this file, which is a profile of npm update, and then load it or drop it in the moar profile viewer web app:

If you don't feel comfortable sending a .cpuprofile file over the intertubes, you can clone the moar-profile-viewer repo and open the docs/index.html page on your own machine - it's a single page app in an .html file - no server required.

There's a bunch of cleanup to do with the viewer, but I'd like for it to serve as a basis for further investigation. The cool thing with both moar-profiler and the moar profile viewer is that they work with existing v8 profile tools. If you really need a flame chart from a profile generated with moar-profiler, just load it into your flavorite profile visualizer (eg, Chrome DevTools). Likewise, the moar profile viewer can read profiles generated with other Node.js profiling tools, but you won't have as nice of an experience compared to profiles generated with moar-profiler.

I do want to provide the ability to see call stacks, somehow. Current thought is Graphviz visualizations of the call stacks involving a selected function. Those might be small enough to provide useful visualization. Previous experiments rendering the entire profile call graph as a single Graphviz graph were ... disastrous, as most extremely large and complex Graphviz graphs tend to be.

This is all open source, of course, so feel free to chime in and help out. I'm obviously interested in bug reports, but also new feature requests. Dream on!

Monday, March 14, 2016

watching your projects

I'm a big fan of having an "automated build step" as part of the development workflow for a project. Figured I'd share what I'm currently doing with my Node.js projects.

What is an "automated build step"? For me, this mean some "shell" code that gets run when I save files while developing. It may not actually be "building" anything - often I'm just running tests. But the idea is that as I save files in my editor, things are run against the code that I just saved.

So there's basically two concepts here:

  • file watchers - watching for updates to files
  • code runners - when files are updated, run some code

file watchers

I have some history with file watchers - wr, jbuild, cakex. The problem with file watching is that it's not easy. The file watching bits in jbuild and cakex are also bundled with other build-y things, which is good and bad - basically bad because you have to buy in to using jbuild and cakex exclusively. wr is a little better in that it's just a file watcher/runner, but I ended finding a replacement for that with nodemon. The advantage to using nodemon is that it's already an accepted tool, and I don't have to support it. :-) Thanks Remy!

code runners

There are many options for code runners; make, cake, grunt, gulp, npm scripts, etc. I'm currently using npm scripts, because they're the easiest thing to do, for non-complex "build steps".

For example, here are the scripts defined in the package.json of the nsolid-statsd package.

"scripts": {
  "start": "node daemon",
  "utest": "node test/index.js | tap-spec",
  "test": "npm run utest && standard",
  "watch": "nodemon --exec 'npm test' --ext js,json"
}

Everything's kicked off by the watch script. It watches for file changes - in this case, changes to .js and .json files, and runs npm test when file changes occur. npm test is defined to run the test script, and for this package, that means running npm run utest and then standard. utest is the final leg of the scripts here, which runs my tape tests rooted at test/index.js, piping them through tap-spec for colorization, etc.

So the basic flow will be this, when running the watch script:

  • run node test/index.js, piping through tap-spec
  • if that passes, run standard
  • wait for a .js or .json file to change
  • when one of those files changes, start over from the beginning

Just run the watch script in a dedicated terminal window, perhaps beside your editor, and start editing and saving files.

Note that nodemon, standard and tap-spec are available in the local node_modules directory, because they are devDependencies in the package itself (tape is used when running test/index.js):

"devDependencies": {
  "nodemon": "~1.8.1",
  "tape": "~4.2.0",
  "tap-spec": "~4.1.1",
  "standard": "~5.4.1"
}

As such, I can use their 'binaries' directly in the npm scripts.

command line usage

You would then kick this all off by running npm run watch. But since it turns out I've been adding a watch script to projects for a long time, all of which do basically the same thing (maybe with different tools), I instead wrote a bash script a while back called watch:

#!/bin/sh
npm run watch

So now I just always run watch in the project directory to start my automated build step.

Here's what the complete workflow looks like:

  • open a terminal in the project directory
  • open my editor (Atom)
  • run watch at the command-line
  • see the tests runs successfully
  • make a change by adding a blank line that standard will provide a diagnostic for
  • save file
  • see tests run, see message from standard
  • remove blank line, save file
  • see tests run, no message from standard

(open image in a new window)

It's basically an IDE using the command-line and your flavorite editor, and I love it.

As projects get more complex, I'll start using some additional tooling like make, cake, etc, or just invoke stand-alone bash or node scripts available in a tools directory. Those would just get added as new npm scripts, and injected into the script flow with nodemon. For instance, you might do something like this:

"scripts": {
  "start": "node daemon",
  "utest": "node test/index.js | tap-spec",
  "test": "npm run utest && standard",
  "build": "tools/build.sh",
  "build-test": "npm run build && npm test",
  "watch": "nodemon --exec 'npm run build-test' --ext js,json"
}

Now when I watch, tools/build.sh will be run before the tests. You can also run each of these steps individually, via npm run build, npm test, npm run utest, etc.

Monday, September 28, 2015

getting started with N|Solid at the command line

Last week, NodeSource (where I work) announced a new product, N|Solid . N|Solid is a platform built on Node.js that provides a number of enhancements to improve troubleshooting, debugging, managing, monitoring and securing your Node.js applications.

N|Solid provides a gorgeous web-based console to monitor/introspect your applications, but also allows you to introspect your Node.js applications, in the same way, at ye olde command line.

Let's explore that command line thing!

installing N|Solid Runtime

In order to introspect your Node.js applications, you'll run them with the N|Solid Runtime, which is shaped similarly to a typical Node.js runtime, but provides some additional executables.

To install N|Solid Runtime, download and unpack an N|Solid Runtime tarball (.tar.gz file) from the N|Solid download site. For the purposes of this blog post, you'll only need to download N|Solid Runtime; the additional downloads N|Solid Hub and N|Solid Console are not required.

On a Mac, you can alternatively download the native installer .pkg file. If using the native installer, download the .pkg file, and then double-click the downloaded file in Finder to start the installation. It will walk you through the process of installing N|Solid Runtime in the usual Node.js installation location, /usr/local/bin.

If you just want to take a peek at N|Solid, the easiest thing is to download a tarball and unpack it. On my mac, I downloaded the "Mac OS .tar.gz" for "N|Solid Runtime", and then double-clicked on the .tar.gz file in Finder to unpack it. This created the directory nsolid-v1.0.1-darwin-x64. Rename that directory to nsolid, start a terminal session, cd into that directory, and prepend it's bin subdirectory to the PATH environment variable:

$ cd Downloads/nsolid
$ PATH=./bin:$PATH
$ nsolid -v
v4.1.1
$

In the snippet above, I also ran nsolid -v to print the version of Node.js that the N|Solid Runtime is built on.

This will make the following executables available on the PATH, for this shell session:

  • nsolid is the binary executable version of Node.js that N|Solid ships
  • node is a symlink to nsolid
  • npm is a symlink into lib/node_modules/npm/bin/npm-cli.js, as it is with typical Node.js installs
  • nsolid-cli is a command-line interface to the N|Solid Agent, explained later in this blog post

Let's write a hello.js program and run it:

$ echo 'console.log("Hello, World!")' > hello.js
$ nsolid hello
Hello, World!
$

Success!

the extra goodies

N|Solid Runtime version 1.0.1 provides the same Node.js runtime as Node.js 4.1.1, with some extra goodies. Anything that can run in Node.js 4.1.1, can run in N|Solid 1.0.1. NodeSource will release new versions of N|Solid as new releases of Node.js become available.

So what makes N|Solid different from regular Node.js?

If you run nsolid --help, you'll see a listing of additional options and environment variables at the end:

$ nsolid --help
...
{usual Node.js help here}
...
N|Solid Options:
  --policies file       provide an NSolid application policies file

N|Solid Environment variables:
NSOLID_HUB              Provide the location of the NSolid Hub
NSOLID_SOCKET           Provide a specific socket for the NSolid Agent listener
NSOLID_APPNAME          Set a name for this application in the NSolid Console
$

N|Solid policies allow you to harden your application in various ways. For example, you can have all native memory allocations zero-filled by N|Solid, by using the zeroFillAllocations policy. By default, Node.js does not zero-fill memory it allocates from the operating system, for performance reasons.

For more information on policies, see the N|Solid Policies documentation.

Besides policies, the other extra goody that N|Solid provides is an agent that you can enable to allow introspection of your Node.js processes. To enable the N|Solid Agent, you'll use the environment variables listed in the help text above.

For the purposes of the rest of this blog post, we'll just focus on interacting with a single Node.js process, and will just use the NSOLID_SOCKET environment variable. The NSOLID_HUB and NSOLID_APPNAME environment variables are used when interacting with multiple Node.js processes, via the N|Solid Hub.

The N|Solid Agent is enabled if the NSOLID_SOCKET environment variable is set, and is not enabled if the environment variable is not set.

Let's start a Node.js REPL with the N|Solid Agent enabled:

$ NSOLID_SOCKET=5000 nsolid
> 1+1 // just show that things are working
2
>

This command starts up the typical Node.js REPL, with the N|Solid Agent listening on port 5000. When the N|Solid Agent is enabled, you can interact with it using N|Solid Command Line Interface (CLI), implemented as the nsolid-cli executable.

running nsolid-cli commands

Let's start with a ping command. Leave the REPL running, start a new terminal window, cd into your nsolid directory again, and set the PATH environment variable:

$ cd Downloads/nsolid
$ PATH=./bin:$PATH
$

Now let's send the ping command to the N|Solid Agent running in the REPL:

$ nsolid-cli --socket 5000 ping
"PONG"
$

In this case, we passed the --socket option on the command line, which indicates the N|Solid Agent port to connect to. And we told it to run the ping command. The response was the string "PONG".

The ping command just validates that the N|Solid Agent is actually running.

Let's try the system_stats command, with the REPL still running in the other window:

$ nsolid-cli --socket 5000 system_stats
{"freemem":2135748608,"uptime":2414371,"load_1m":1.17431640625,"load_5m":1.345703125,"load_15m":1.3447265625,"cpu_speed":2500}
$

The system_stats command provides some system-level statistics, such as amount of free memory (in bytes), system uptime, and load averages.

The output is a single line of JSON. To make the output more readable, you can pipe the output through the json command, available at npm:

$ nsolid-cli --socket 5000 system_stats | json
{
  "freemem": 1970876416,
  "uptime": 2414810,
  "load_1m": 1.34765625,
  "load_5m": 1.26611328125,
  "load_15m": 1.29052734375,
  "cpu_speed": 2500
}
$

Another nsolid-cli command is process_stats, which provides some process-level statistics:

$ nsolid-cli --socket 5000 process_stats | json
{
  "uptime": 2225.215,
  "rss": 25767936,
  "heapTotal": 9296640,
  "heapUsed": 6144552,
  "active_requests": 0,
  "active_handles": 4,
  "user": "pmuellr",
  "title": "nsolid",
  "cpu": 0
}
$

The full list of commands you can use with nsolid-cli is available at the doc page N|Solid Command Line Interface (CLI) .

generating a CPU profile

Let's try one more thing - generating a CPU profile. Here's a link to a sample program to run, that will keep your CPU busy: busy-web.js

This program is an HTTP server that issues an HTTP request to itself, every 10 milliseconds. It makes use of some of the new ES6 features available in Node.js 4.0, like template strings and arrow functions. Since the N|Solid Runtime is using the latest version of Node.js, you can make use of those features with N|Solid as well.

Let's run it with the agent enabled:

$ NSOLID_SOCKET=5000 nsolid busy-web
server listing at http://localhost:53011
send: 100 requests
recv: 100 requests
...

In another terminal window, run the profile_start command, wait a few seconds and run the profile_stop command, redirecting the output to the file busy-web.cpuprofile:

$ nsolid-cli --socket 5000 profile_start
{"started":1443108818350,"collecting":true}
... wait a few seconds ...
$ nsolid-cli --socket 5000 profile_stop > busy-web.cpuprofile

The file busy-web.cpuprofile can then be loaded into Chrome Dev Tools for analysis:

  • in Chrome, select the menu item View / Developer / Developer Tools
  • in the Developer Tools window, select the Profiles tab
  • click the "Load" button
  • select the busy-web.cpuprofile file
  • in the CPU PROFILES list on the left, select "busy-web"

For more information on using Chrome Dev Tools to analyze a CPU profile, see Google's Speed Up JavaScript Execution page.

Note that we didn't have to instrument our program with any special profiling packages - access to the V8 CPU profiler is baked right into N|Solid! About time someone did that, eh?

You can easily write a script to automate the creation of a CPU profile, where you add a sleep command to wait some number of seconds between the profile_start and profile_stop commands.

#!/bin/sh

echo "starting CPU profile"
nsolid-cli --socket 5000 profile_start

echo "waiting 5 seconds"
sleep 5

echo "writing profile to busy-web.cpuprofile"
nsolid-cli --socket 5000 profile_stop > busy-web.cpuprofile

Or instead of sleeping, if your app is an HTTP server, you can drive some traffic to it with Apache Bench (ab), by running something like this instead of the sleep command:

ab -n 1000 -c 100 http://localhost:3000/

generating heap snapshots

You can use the same technique to capture heap snapshots, using the snapshot command. The snapshot command produces output which should be redirected to a file with a .heapsnapshot extension:

$ nsolid-cli --socket 5000 snapshot > busy-web.heapsnapshot

You can then load those files in Chrome Dev Tools for analysis, the same way the CPU profiles are loaded.

For more information on using Chrome Dev Tools to analyze a heap snapshot, see Google's How to Record Heap Snapshots page.

more info

The full list of commands you can use with nsolid-cli is available at the doc page N|Solid Command Line Interface (CLI) .

All of the documentation for N|Solid is available at the doc site N|Solid Documentation.

If you have any questions about N|Solid, feel free to post them at Stack Overflow, and add a tag nsolid.

Wednesday, May 13, 2015

resuscitating a 2006 MacBook

One bad assumption I made about leaving IBM is that I'd be able to get a new MacBook Pro quickly. Nope. 2-3 weeks. NO LAPTOP! HOW AM I SUPPOSED TO TAKE TIME OFF AND RELAX?

Poking through my shelves of computer junk, I spied my two old MacBooks. I forgot I had two of them.

The first was a G4 (PPC) iBook. That was the laptop I bought in 2003 to kick the tires on Apple hardware and OS X 10.2. I was hooked.

The second was a Intel Core Duo (x86) MacBook. 2 2Ghz x86 cores, 2GB RAM, 120GB drive. I bought that in 2006, and remember it being a productive machine. Eventually replaced that with a line of MacBook Pros IBM provided me, up until this week.

Hmmm, is that MacBook still usable? Powered it up fine. Poking around, it seemed like constraints on hardware / OS levels were that I should try to get this box from OS X 10.5 to 10.6. Also - this being a 32-bit machine - some number of apps wouldn't run. Eg, Chrome.

Luckily I still had an OS X 10.6 DVD lying around in my piles of old stuff. Upgraded easily. So now I can run PathFinder, Sublime, iTerm, Firefox, and Skype. Can't run Chrome, Atom, or Twitter. Or io.js. Again, HOW AM I SUPPOSED TO TAKE TIME OFF AND RELAX?

The build requirements for io.js looked like something that I might be able to meet. Rolled up my sleeves.

First I wanted to update git. Currrent version was at 1.6. It was already complaining about git clone operations on occasion. So, first installed homebrew, then installed git 2.4.

That was easy. Now to install gcc/g++ - they were not already on the machine, and the latest stable at brew is 4.9.2. After a long time, it installed that fine. But it doesn't override the built-in gcc/g++. Instead, it provides gcc-4.9 and similar named tools for that version of the gcc toolchain.

To get the iojs Makefile to use these instead of the built-in gcc tools, I set env vars in my .bash_profile:

export CC=gcc-4.9
export CXX=g++-4.9
export AR=gcc-ar-4.9
export NM=gcc-nm-4.9
export RANLIB=gcc-ranlib-4.9

Ready to build iojs! Ran ./configure - it completed successfully but was a little complain-y about some unrelated looking things. Ran make. And then fell asleep. Woke up, it had completed successfully, so ran a little test and ... WORKED! Finally ran sudo make install and NOW IT IS EVERYWHERE.

Got some test failures, but they may be environmental. Tried some typical workflow stuff and things seem fine.

Not a dream machine, by any means. Slow. Constantly watching memory usage and quitting apps as appropriate. And the fan is quite noisy. And the display seems like it doesn't have long to live (display adapter problems are my lot in life as a MacBook owner).

But kinda fun.

leaving IBM, taking a break, going somewhere else

This last Monday - May 11, 2015 - was my last day as an IBMer.

I had a great run at IBM. Worked on a lot of great, diverse projects with great people.

But I'm ready for a change. I've been planning on retiring this year, for a while now, but it kinda snuck up on me. Mid-life crisis? Maybe. Anyway, it's time!

First, a breather.

Then, looking forward to starting my next adventure(s) in software development.

I'm talking to some potential employers right now, and would like to talk to more. Contact info is in my resume, linked to below.

In terms of what I'm looking for, I'd like to continue working in the node.js environment. Still having a lot of fun there. My favorite subject matter is working on tools for developers. But I'm handy - and interested - in lots of stuff.

I live in the Raleigh/NC area, and can't relocate for a few years. I'm quite comfortable working remote, or local.

My resume is available here:

http://muellerware.org/resume/Patrick-Mueller-Resume.html

Thursday, March 26, 2015

wiki: something old, something new

Back in 1995, Ward Cunningham - a fellow BoilerMaker - created a program called WikiWikiWeb, which created a new species of web content we now know as the "wiki".

My colleague Rick DeNatale showed it to me, and I was hooked. So hooked, I wrote a clone in REXX for OS/2, which I've sadly been unable to find. It's funny to see the names of some other friends on list of initial visitors.

Since then, I've always had some manner of wiki in my life. We still use wikis to document project information in IBM, I use Wikipedia all the time for ... whatever ..., and occaisonally use the free wiki service that GitHub provides for projects there. I think some credit also goes to Ward for helping push the "simplied html markup" story (eg, Markdown), to make editing and creating web content more approachable to humans.

Ward started a new project a few years back, Smallest Federated Wiki, to start exploring some interesting aspects of the wiki space - federating wikis, providing plugin support, multi-page views, rich change history. It's fascinating.

I've had in the back of my mind to get Federated Wiki to run on Bluemix for a while, and it seemed like an appropriate time to make something publishable. So, I created the cf-fed-wiki project, which will let you easily deploy a version of Federated Wiki on Cloud Foundry (and thus Bluemix), and is also set up to use with the new easy-to-deploy Bluemix Button (below).

Deploy to Bluemix

There are still some rough spots, but it seems workable, or at least something to play with.

The best way to learn about Federated Wiki is to watch Ward's videos.

Enjoy, and thanks for the wiki, Ward!

Friday, February 13, 2015

having your cake and cakex'ing it too

As a software developer, I care deeply about my build tools. I strive to provide easy-to-use and understand build scripts with my projects, so that other folks can rebuild a project I'm working on, as simply as possible. Often one of those other folks is me, coming back to a project after being away for it for months, or years.

I cut my teeth on make. So awesome, for it's time. Even today, all kinds of wonderful things about it. But there are problems. Biggest is ensuring Makefile compatibility across all the versions of make you might encounter. I've used make on OS/2, Windows, AIX, Linux, Mac, and other Unix-y platforms. The old version of Windows nmake was very squirrelly to deal with, and if you had to build a Makefile that could run on Windows AND anywhere else, well best of luck, mate! make is also a bit perl-ish with all the crazy syntax-y things you can do. It's driven me to near-insanity at times.

I was also a big user of Ant. I don't do Java anymore, and would prefer to not do XML either, but I do still build weinre with Ant.

Since I'm primarily doing node.js stuff these days, it makes a lot of sense to use a build tool implemented on node.js; I've already got the runtime for that installed, guarantee. In the past, I've used jake with the Apache Cordova project, and have flirted with the newest build darlings of the node.js world, grunt and gulp.

I tend towards simpler tools, and so am happier at the jake level of simple-ness comared to the whole new way of thinking required to use grunt or gulp, which also have their own sub-ecosystem of plugins to gaze upon.

Of course, there are never enough build tools out there, so I've also built some myself: jbuild. I've been using jbuild for projects since I built it, and have been quite happy with it. But, it's my own tool, I don't really want to own a tool like this. The interesing thing about jbuild was the additional base level functionality it provided to the actual code you'd write in your build scripts, and not the way tasks were defined and what not.

As a little experiment, I've pulled that functionality out of jbuild and packaged up as something you can use easily with cake. cake is one the simplest tools out there, in terms of what it provides, and let's me write in CoffeeScript, which is closer to the "shell scripting" experience with make (which is awesome) compared to most other build tools.

Those extensions are in the cakex package available via npm.

why cakex

  • shelljs function built in as globals. So I can do things like

    mkdir "-p", "tmp"
    rm   "-rf", "tmp"
    

    (that's CoffeeScript) right in my Cakefile. Compare to how you'd do that in Ant. heh.

  • scripts in node_modules/.bin added as global functions that invoke those scripts. Hat tip, npm run. So I can do things like

    opts = """
      --outfile    tmp/#{oBase}
      --standalone ragents
      --entry      lib/ragents.js
      --debug
    """
    
    opts = opts.trim().split(/\s+/).join(" ")
    
    log "running browserify ..."
    browserify opts
    
  • functions acting as watchers, and server recyclers. I always fashion build scripts to that they have a watch task, which does a build, runs tests, restarts the server that's implemented in the project, etc. So that when I save a file in my text editor, the build/test/server restart happens all the time. These are hard little things to get right; I know, I've been trying for years to get them right. Here's an example usage:

    taskWatch = ->
      watchIter()          # run watchIter when starting
    
      watch
        files: sourceFiles # watch sourceFiles for changes
        run:   watchIter   # run watchIter on changes
    
    watchIter = ->
      taskBuild()          # run the build
      taskServe()          # run the server
    
    taskServe = ->
      log "restarting server at #{new Date()}"
    
      # starts / restarts the server, whichever is needed
      daemon.start "test server", "node", ["lib/server"]
    

The cakex npm page - https://www.npmjs.com/package/cakex - includes a complete script that is the kind of thing I have in all my projects, so you can take in the complete experience. I love it.

Coupla last things:

  • yup, globals freaking everywhere. It's awesome.

  • I assume this would be useful with other node.js-based build tools, but wouldn't surprise me if the "globals everywhere" strategy causes problems with other tools.

  • I'm using gaze to watch files, but it appears to have a bug where single file patterns end up matching too many things; hence having to do extra checks when you're watching a single file.

  • I've wrestled with the demon that are the daemon functions in cakex for a long time. Never completely happy with any story there, but it's usually possible to add enough hacks to keep things limping. Wouldn't be surprised if I have to re-architect the innards there, again, but hopefully the API can remain the same.

  • Please also check the section in the README titled "integration with npm start", for what I believe to be a best practice of including all your build tools as dependencies in your package, instead of relying on globally installed tools. For node.js build tools anyway.

Thursday, January 01, 2015

ragents against the machine

A few years back, I developed a tool called web inspector remote - aka weinre. It's an interesting hack where I took the WebKit Web Inspector UI code, ran it in a plain old (WebKit-based) browser, and hooked things up so it could debug a web browser session running somewhere else. I was specifically targeting mobile web browsers and applications using web browser views, but there wasn't much (any?) mobile-specific code in weinre.

(btw, I currently run a publicly accessible weinre server at Bluemix)

One of the interesting aspects of weinre, is the way the browser running the debugger user interface (the client) communicates with the browser being debugged (the target). The WebKit Web Inspector code was originally designed so that the client would connect to the target in a traditional client/server pattern. But on mobile devices, or within a web browser environment, it's very difficult to run any kind of a tradtional "server" - tcp, http, or otherwise.

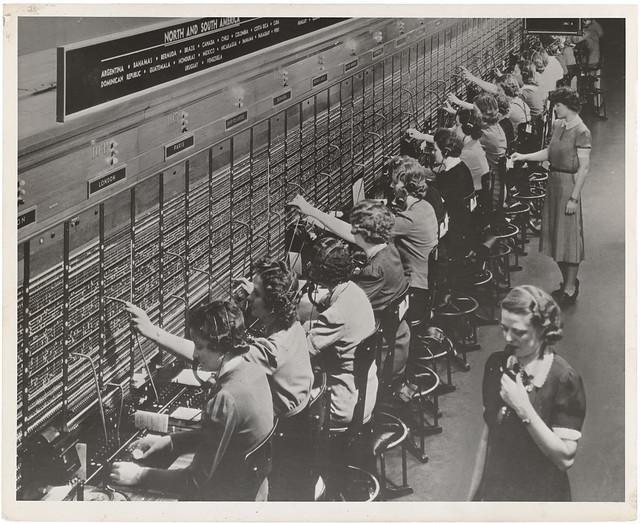
So the trick to make this work with weinre, is to have both the client and target connect as HTTP clients to an HTTP server that shuttles messages between the two. That HTTP server is the weinre server. It's basically just a message switchboard between debug clients and targets.

Photograph of Women Working at a Bell System Telephone Switchboard

This switchboard server pattern is neat, because it allows two programs to interact with each other, where neither has to be an actual "server" of any kind (tcp, http, etc).

And this turns out to be a useful property in other environments as well. For instance, dealing with server farms running "in the cloud". Imagine you're running some kind of web application server, and decide to run 5 instances of your server to handle the load. And now you want to "debug" the server. How do you connect to it? Presumably the 5 instances are running behind one ip address - which server instance are you going to connect to? How could you connect to all of them at once?

Instead of using the typical client/server pattern for debugging in this environment, you can use the switchboard server pattern, and have each web application server instance connect to the switchboard server itself, and then have a single debug client which can communicate with all of the web application server instances.

I've wanted to extract the switchboard server pattern code out of weinre for a while now, and ... nows the time. I anticipate being able to define a generic switchboard server, and messaging protocol that can be used to allow multiple, independent, orthagonal tools to communicate with each other, where the tools are running in various environments. The focus here isn't specifically traditional graphical step debugging, but diagnostic tooling in general. Think loggers, REPLs, and other sorts of development tools.

One change I've made as part of the extraction is terminology. In weinre, there were "clients" and "targets" that had different capabilities. But there really doesn't need to be a distinction between the two, in terms of naming or functionality. Instead, I'm referring to these programs as "agents".

And sometimes agents will be communicating with agents running on other computers - remote agents - "ragents" - hey, that would be a cool name for a project!

Another thing I'm copying from the Web Inspector work is the messaging protocol. At the highest level, there are two types of messages that agents can send - request/response pairs, and events.

  • A request message can be sent from one agent to another, and then a response message is sent the opposite direction. Like RPC, or an HTTP request/response.

  • An event message is like a pub/sub message; multiple agents can listen for events, and then when an agent posts an event message, it's sent to every agent that is listening.

You can see concrete examples of these request/response and event messages in the V8 debugger protocol and the Chrome Remote Debugging Protocol.

This pattern makes it very easy to support things like having multiple debugger clients connect to a single debug target; all state change in the target gets emitted as events so every connected client will see the change. But you can also send specific requests from the client to the target, and only the client will see the responses.

For example, one debugger client might send a request "step" to have the debugger execute the next statement then pause. The response for this might be just a success/failure indicator. A set of events would end up being posted that the program started, and then stopped again (on the next statement). That way, every debugger client connected would see the effects of the "step" request.

Turns out, you really need to support multiple clients connected simultaneously if your clients are running in a web browser. Because if you only support a single client connection to your program, what happens when the user can't find their browser tab running the client? The web doesn't want to work with singleton connections.

I'm going to be working on the base libraries and server first, and then build some diagnostic tools that make use of them.

Stay tuned!

Wednesday, September 10, 2014

keeping secrets secret

If you're building a web app, you probably have secrets you have to deal with:

  • database credentials
  • session keys
  • etc

So, where do you keep these secrets? Typical ways are:

  • hard-code them into your source
  • require them to be passed on the command-line of your program
  • get them from a config file
  • get them from environment variables

Folks using Cloud Foundry based systems have another option:

This blog post will go over the advantages and disadvantages of these approaches. Examples are provided for node.js, but are applicable to any language.

secrets via hard-coding

The documentation for the express-session package shows the following example of hard-coding your secrets into your code:

This is awful:

  • If you need to change the secret, you need to change the code; apply some separation of concerns, and keep your code separate from your configuration.

  • If you happen to check this code into a source code management (SCM) system, like GitHub, then everyone with access to that SCM will have access to your password. That might be literally everyone.

Please, DO NOT DO THIS!!

Don't be one of these people. Use one of the techniques below, instead.

secrets via config files

Here is an example using require() to get a secret from a JSON file:

This example takes advantage of the node.js feature of being able to load a JSON file and get the parsed object as a result.

If you're going to go this route, you should do the following:

  • Do NOT store the config file in your SCM, because otherwise you may still be making your secret available to everyone who has access to your SCM.

  • To keep the config file from being stored, add the file to your .gitignore file (or equivalent for your SCM).

  • Create an example config file, say secret-config-sample.json, which folks can copy to the actual secret-config.json file, and use as an example.

  • Document the example config file usage.

You now have an issue of how to "manage" or save this file, since it's not being stored in an SCM.

secrets via command-line arguments

Here is an example using the nopt package to get a secret from a command-line argument:

You can then invoke your program using either of these commands:

node secret-arg.js --sessionSecret "keyboard cat"
node secret-arg.js -s "keyboard cat"

This is certainly nicer than having secrets hard-coded in your app, but it also means you will be typing the secrets a lot. If you decide to "script" the command invocation, keep in mind your script now has your secrets in it. Use the "example file" pattern described above in "secrets via config files" to keep the secret out of your SCM.

secrets via environment variables

Here is an example using process.env to get a secret from an environment variable:

You can then invoke your program using the following command:

SESSION_SECRET="keyboard cat" node secret-env.js

Like using command-line arguments, if you decide to script this, keep in mind your secret will be in the script.

You likely have other ways of setting environment variables when you run your program. For instance, in Cloud Foundry, you can set environment variables via a manifest.yml file or with the cf set-env command.

If you decide to set the environment variable in your manifest.yml file, keep in mind your secret will be in the manifest. Use the "example file" pattern described above in "secrets via config files" to keep the secret out of your SCM. Eg, put manifest.yml in your .gitignore file, and ship a manifest-sample.yml file instead.

secrets via Cloud Foundry user-provided services

Here is an example using the cfenv package to get a secret from a user-provided service:

This is my favorite way to store secrets for Cloud Foundry. In the example above, the code is expecting a service whose name matches the regular expression /session-secret/ to contain the secret in the credentials property named secret. You can create the user-provided service with the cf cups command:

cf cups a-session-secret-of-mine -p secret

This will prompt you for the value of the property secret, and then create a new service named a-session-secret-of-mine. You will need to cf bind the service to your application to get access to it.

There are a number of advantages to storing your secrets in user-provided services:

  • A service can be bound to multiple applications; this is a great way to store secrets that need to be shared by "micro-services", if you're into that kind of thing.

  • Once created, these values are persistent until you delete the service or use the new cf uups command to update them.

  • These values are only visible to users who have the appropriate access to the service.

  • Using regular expression matching for services makes it easy to switch services by having multiple services with regexp matchable names, and binding only the one you want. See my project bluemix-service-switcher for an example of doing this.

secrets via multiple methods

Of course, for your all singing, all dancing wunder-app, you'll want to allow folks to configure secrets in a variety of ways. Here's an example that uses all of the techniques above - including hard-coding an undefined value in the code! That should be the only value you ever hard-code. :-)

The example uses the defaults() function from underscore to apply precedence for obtaining a secret from multiple techniques.

Wednesday, September 03, 2014

cfenv 1.0.0 with new getServiceCreds() method

I've updated the node.js cfenv package at npm:

  • moved from the netherworld of 0.x.y versioned packages to version 1.0.0
  • updated some of the package dependencies
  • added a new appEnv.getServiceCreds(spec) method

In case you're not familiar with the cfenv package, it's intended to be the swiss army knife of handling your Cloud Foundry runtime environment variables, including: PORT, VCAP_SERVICES, and VCAP_APPLICATION.

Here's a quick example that doesn't including accessing services in VCAP_SERVICES:

You can start your server with this kind of snippet, which provides the correct port, binding address, and url of the running server; and it will run locally as well as on CloudFoundry.

For more information, see the cfenv readme.

new API appEnv.getServiceCreds(spec)

Lately I've been finding myself just needing the credentials property value from service objects. To make this just a little bit easier than:

you can now do this, using the new appEnv.getServiceCreds(spec) API:

No need to get the whole service if you don't need it, and you don't have to type out credentials all the time :-)

what else?

What other gadgets does cfenv need? If you have thoughts, don't hesitate to open an issue, send a pull request, etc.

Friday, June 06, 2014

debugging node apps running on Cloud Foundry

For node developers, the node-inspector package is an excellent tool providing debugger support, when you need it. It reuses the Chrome DevTools debugger user interface, in the same kinda way my old weinre tool for Apache Cordova does. So if you're familiar with Chrome DevTools when debugging your web pages, you'll be right at home with node-inspector.

If you haven't tried node-inspector in a while, give it another try; the new-ish node-debug command orchestrates the dance between your node app, the debugger, and your browser, that makes it dirt simple to get the debugger launched.

Lately I've been doing node development with IBM's Bluemix PaaS, based on the Cloud Foundry. And wanting to use node-inspector. But there's a problem. When you run node-inspector, the following constraints are in play:

  • you need to launch your app in debug mode
  • you need to run node-inspector on the same machine as the app
  • node-inspector runs a web server which provides the UI for the debugger

All well and good, except if the app you are trying to debug is a web server itself. Because with CloudFoundry, an "app" can only use one HTTP port - but you need two - one for your app and one for node-inspector.

And so, the great proxy-splitter hack.

Here's what I'm doing:

  • instead of running the actual app, run a shell app
  • that shell app is a proxy server
  • launch the actual app on some rando port, only visible on that machine
  • launch node inspector on some rando port, only visible on that machine
  • have the shell app's proxy direct traffic to node-inspector if the incoming URL matches a certain pattern
  • for all other URLs the shell app gets, proxy to the actual app

AND IT WORKS!

And then imagine my jaw-dropping surprise, when last week at JSConf, Mikeal Rogers did a presentation on his occupy cloud deployment story, which ALSO uses a proxy splitter to do it's business.

This is a thing, I think.

I've cobbled the node-inspector proxy bits together as cf-node-debug. Still a bit wobbly, but I just finished adding some security support so that you need to enter a userid/password to be able to use the debugger; you don't want strangers on the intertubes "debugging" your app on your behalf, amirite?

This works on BlueMix, but doesn't appear to work correctly on Pivotal Web Services; something bad is happening with the web sockets; perhaps we can work through that next week at Cloud Foundry Summit?

Monday, May 19, 2014

enabling New Relic in a Cloud Foundry node application

Something you will want to enable with your apps running in a Cloud Foundry environment such as BlueMix, is monitoring. You'll want a service to watch your app, show you when it's down, how much traffic it's getting, etc.

One such popular service is New Relic.

Below are some instructions showing how you can enable a node.js application to optionally make use of monitoring with New Relic, and keep hard-coded names and license keys out of your source code.

The documentation for using New Relic with a node application is available in the Help Center documentation "Installing and maintaining Node.js".

But we're going to make a few changes, to make this optional, and apply indirection in getting your app name and license key.

  • instead of copying node_modules/newrelic/newrelic.js to the root directory of your app, create a newrelic.js file in the root directory with the following contents:
  • This module is slightly enhanced from the version that New Relic suggests that you create (see https://github.com/newrelic/node-newrelic/blob/master/newrelic.js). Rather than hard-code your app name and license key, we get them dyanmically.

  • The app name is retrieved from your package.json's name property; and the license key is obtained from an environment variable. Note this code is completely portable, and can be copied from one project to another without having to change keys or names.

  • To set the environment variable for your CloudFoundry app, use the command

    cf set-env <app-name> NEW_RELIC_LICENSE_KEY 983498129....
    
  • To run the code in the initialize() function, use the following code in your application startup, as close to the beginning as possible:

  • This code is different than what you what New Relic suggests you use at the beginning of your application code; instead of doing the require("newrelic") directly in your code, it will be run via the require("./newrelic").initialize() code.

  • If you don't have the relevant environment variable set, then New Relic monitoring will not be enabled for your app.

Another option to keeping your license key un-hard-coded and dynamic is to use a Cloud Foundry service. For instance, you can create a user-provided service instance using the following command:

cf cups NewRelic -p '{"key":"983498129...."}'

You can then bind that service to your app:

cf bind-service <app-name> NewRelic

Your application code can then get the key from the VCAP_SERVICES environment variable.

I would actually use services rather than environment variables in most cases, as services can be bound to multiple apps at the same time, whereas you need to set the environment variables for each app.

In this case, I chose to use an environment variable, as you really should be doing the New Relic initialization as early as possible, and there is less code involved in getting the value of an environment variable than parsing the VCAP_SERVICES values.

You may want to add some other enhancements, such as appending a -dev or -local suffix to the app name if you determine you're running locally instead of within Cloud Foundry.

I've added optional New Relic monitoring to my node-stuff app, so you can see all this in action in the node-stuff source at GitHub.


update on 2014/05/19

After posting this blog entry, Chase Douglas (@txase) from New Relic tweeted that "the New Relic Node.js agent supports env vars directly", pointing to the New Relic Help Center doc "Configuring Node.js with environment variables".

Thanks Chase. Guess I need to learn to RTFM!

What this means is that you can most likely get by with a much easier set up if you want to live the "environment variable configuration" life. There may still be some value in a more structured approach, like what I've documented here, if you'd like to be a little more explicit.

Also note that I specified using an environment variable of NEW_RELIC_LICENSE_KEY, which is the exact same name as the environment variable that the New Relic module uses itself! (Great minds think alike?) As such, it would probably be a good idea, if you want to do explicit configuration as described here, to avoid using NEW_RELIC_* as the name of your environment variables, as you may get some unexpected interaction. In fact, my read of the precedence rules are that the environment variables override the newrelic.js config file settings, so the setting in the newrelic.js is ignored in favor of the environment variable, at least in this example.

Tuesday, April 15, 2014

my new job at IBM involving node.js

Over the last year, as my work on weinre (part of the Apache Cordova project) has wound way down, folks have been asking me "What are you working on now?"

The short answer was "cloud stuff". The long answer started with "working with the Cloud Foundry open source PaaS project".

IBM has been involved in the Cloud Foundry project for a while now. I've been working on different aspects of using Cloud Foundry, almost all of them focused around deploying node.js applications to Cloud Foundry-based platforms.

About a month and a half ago, IBM announced our new BlueMix PaaS offering1, based on Cloud Foundry.

And as of a few weeks ago, I've taken a new job at IBM that I call "Developer Advocate for BlueMix, focusing on node.js". Gotta word-smith that a bit. In this role, I'll continue to be able to work on different aspects of our BlueMix product and the open source Cloud Foundry project, using node.js, only this time, more in the open.

This is going to be fun.

I already have a package up at npm - cf-env - which makes it a bit easier to deal with your app's startup configuration. It's designed to work with Cloud Foundry based platforms, so works with BlueMix, of course.

I've also aggregated some node.js and BlueMix information together into a little site, hosted on BlueMix:

http://node-stuff.mybluemix.net

I plan on working on node.js stuff relating to:

  • things specifically for BlueMix
  • things more generally for Cloud Foundry
  • things more generally for using any PaaS
  • things more generally for using node.js anywhere

I will be posting things specific to BlueMix on the BlueMix dev blog, and more general things on this blog.

If you'd like more information on using node.js on BlueMix or CloudFoundry, don't hesitate to get in touch with me. The easiest ways are @pmuellr on twitter, or email me at Patrick_Mueller@us.ibm.com.

Also, did you know that IBM builds it's own version of node.js ? I'm not currently contributing to this project, but I've known the folks that are working on it, for a long time. Like, from the Smalltalk days. :-)


note on weinre

I continue to support weinre. You can continue to use the following link to find the latest information, links to forums and bug trackers, etc.

http://people.apache.org/~pmuellr/weinre/docs/latest/Home.html

I will add that most folks have absolutely no need for weinre anymore; both Android and iOS have great stories for web app debug.

As Brian LeRoux has frequently stated, one of the primary goals of Apache Cordova is to cease to exist. weinre has nearly met that goal.


1 Try Bluemix for free during the beta - https://bluemix.net/

Tuesday, November 12, 2013

gzip encoding and compress middleware

Hopefully everyone who builds stuff for the web knows about gzip compression available in HTTP. Here's a quick intro if you don't: https://developers.google.com/speed/articles/gzip

I use connect or express when building web servers in node, and you can use the compress middleware to have your content gzip'd (or deflate'd), like in this little snippet.

However ...

Let's think about what's going on here. When you use the compress middleware like this, for every response that sends compressable content, your content will be compressed. Every time. Of course, for your "static" resources, the result of that compression is the same every time, and so for those resources, it's really kind of pointless to run the compression for each request. You should do it once, and then reuse that compressed result for future requests.

Here are some tests using the play Waste, by Harley Granville-Barker. I pulled the HTML version of the file, and then also gzip'd the file manually from the command-line for one of tests.

The HTML file is ~300 KB. The gzip'd version is ~90 KB.

And here's a server I built to serve the files:

The server runs on 3 different HTTP ports, each one serving the file, but in a different way.

Port 4000 serves the HTML file with no compression.

Port 4001 serves the HTML file with the compress middleware

Port 4002 serves the the pre-gzip'd version of the file that I stored in a separate directory; the original file was waste.html, but the gzip'd version is in gz/waste.html. It checks the incoming request to see if a gzip'd version of the file exists (caching that result), and internally redirects the server to that file by resetting request.url. Setting the appropriate Content-Encoding, etc headers.

What a hack! Not quite sure that "fixing" request.url is kosher, but, worked great for this test.

Here's some curl invocations.

$ curl --compressed --output /dev/null --dump-header - 
   --write-out "%{size_download} bytes" http://localhost:4000/waste.html

X-Powered-By: Express
Accept-Ranges: bytes
ETag: "305826-1384296482000"
Date: Wed, 13 Nov 2013 01:21:13 GMT
Cache-Control: public, max-age=0
Last-Modified: Tue, 12 Nov 2013 22:48:02 GMT
Content-Type: text/html; charset=UTF-8
Content-Length: 305826
Connection: keep-alive

305826 bytes

Looks normal.

$ curl --compressed --output /dev/null --dump-header - 
   --write-out "%{size_download} bytes" http://localhost:4001/waste.html

X-Powered-By: Express
Accept-Ranges: bytes
ETag: "305826-1384296482000"
Date: Wed, 13 Nov 2013 01:21:13 GMT
Cache-Control: public, max-age=0
Last-Modified: Tue, 12 Nov 2013 22:48:02 GMT
Content-Type: text/html; charset=UTF-8
Vary: Accept-Encoding
Content-Encoding: gzip
Connection: keep-alive
Transfer-Encoding: chunked

91071 bytes

Nice seeing the Content-Encoding and Vary headers, along with the reduced download size. But look ma, no Content-Length header; instead the content comes down chunked, as you would expect with a server-processed output stream.

$ curl --compressed --output /dev/null --dump-header - 
   --write-out "%{size_download} bytes" http://localhost:4002/waste.html

X-Powered-By: Express
Content-Encoding: gzip
Vary: Accept-Encoding
Accept-Ranges: bytes
ETag: "90711-1384297654000"
Date: Wed, 13 Nov 2013 01:21:13 GMT
Cache-Control: public, max-age=0
Last-Modified: Tue, 12 Nov 2013 23:07:34 GMT
Content-Type: text/html; charset=UTF-8
Content-Length: 90711
Connection: keep-alive

90711 bytes

Like the gzip'd version above, but this one has a Content-Length!

Here are some contrived, useless benches using wrk, that confirm my fears.

$ wrk --connections 100 --duration 10s --threads 10 
   --header "Accept-Encoding: gzip" http://localhost:4000/waste.html

Running 10s test @ http://localhost:4000/waste.html
  10 threads and 100 connections
  Thread Stats   Avg      Stdev     Max   +/- Stdev
    Latency    71.72ms   15.64ms 101.74ms   69.82%
    Req/Sec   139.91     10.52   187.00     87.24%
  13810 requests in 10.00s, 3.95GB read
Requests/sec:   1380.67
Transfer/sec:    404.87MB

$ wrk --connections 100 --duration 10s --threads 10 
   --header "Accept-Encoding: gzip" http://localhost:4001/waste.html

Running 10s test @ http://localhost:4001/waste.html
  10 threads and 100 connections
  Thread Stats   Avg      Stdev     Max   +/- Stdev
    Latency   431.76ms   20.27ms 493.16ms   63.89%
    Req/Sec    22.47      3.80    30.00     80.00%
  2248 requests in 10.00s, 199.27MB read
Requests/sec:    224.70
Transfer/sec:     19.92MB

$ wrk --connections 100 --duration 10s --threads 10 
   --header "Accept-Encoding: gzip" http://localhost:4002/waste.html

Running 10s test @ http://localhost:4002/waste.html
  10 threads and 100 connections
  Thread Stats   Avg      Stdev     Max   +/- Stdev
    Latency    48.11ms   10.66ms  72.33ms   67.39%
    Req/Sec   209.46     24.30   264.00     81.07%
  20795 requests in 10.01s, 1.76GB read
Requests/sec:   2078.08
Transfer/sec:    180.47MB

Funny to note that the server using compress middleware actually handles less requests/sec than the one that doesn't compress at all. But this is a localhost test so the network bandwidth/throughput isn't realistic. Still, makes ya think.

Tuesday, October 08, 2013

sourcemap best practices

Source map support for web page debugging has been a thing now for a while. If you don't know what a sourcemap is, Ryan Seddon's article "Introduction to JavaScript Source Maps", provides a technical introduction. The "proposal" for source map seems to be here.

In a nutshell, sourcemap allow you to ship minized .js files (and maybe .css files), which point back to the original source, so that when you debug your code in a debugger like Chrome Dev Tools, you'll see the original source.

It's awesome.

Even better, we're starting to see folks ship source maps with their minized resources. For example, looking at the minized angular 1.2.0-rc.2 js file you can see the sourcemap annotation near the end:

/*
//@ sourceMappingURL=angular.min.js.map
*/

The contents of that .map file looks like this (I've truncated bits of it):

{
"version":3,
"file":"angular.min.js",
"lineCount":183,
"mappings":"A;;;;;aAKC,SAAQ,CAACA,CAAD,...",
"sources":["angular.js","MINERR_ASSET"],
"names":["window","document","undefined",...]
}

You don't need to understand any of this, but what it means is that if you use the angular.min.js file in a web page, and also make angular.min.js.map and angular.js files available, when you debug with a sourcemap-enabled debugger (like Chrome Dev Tools), you'll see the original source instead of the minized source.

But there are a few issues. Although I haven't written any tools to generate source maps, I do consume them in libraries and with tools that I use (like browserify). Sometimes I do a bit of surgery on them, to make them work a little better.

Armed with this experience, I figured I'd post a few "best practices", based on some of the issues I've seen, aimed at folks generating sourcemaps.

do not use a data-url with your sourceMappingURL annotation

Using a data url, which browserify does, ends up creating a huge single line for the sourceMappingURL annotation. Many text editors will choke on this, if you accidently, or purposely edit the file with the annotation.

In addition, using a data-url means the mapping data is uuencoded, which means humans can't read it. The sourcemap data is actually sometimes interesting to look at, for instance, if you want to see what files got bundled with browserify.

Also, including the sourcemap as a data-url means you just made your "production" file bigger, especially since it's uuencoded.

Instead of using a data-url with the sourcemap information inlined, just provide a map file like angular does (described above).

put the sourceMappingURL annotation on a line by itself at the end

In the angular example above, the sourceMappingURL annotation is in a // style comment inside a /* */ style comment. Kinda pointless. But worse, it no longer works with Chrome 31.0.1650.8 beta.

Presumably, Chrome Dev Tools got a bit stricter with how they recognize the sourceMappingURL annotation; it seems to like having the comment at the very end of the file. See https://code.google.com/p/chromium/issues/detail?id=305284 for more info.

Browserify also has an issue here, as it adds a line with a single semi-colon to the end of the file, right before the sourceMappingURL annotation, which also does not work in the version of Chrome I referenced.

name your sourcemap file <min-file>.map.json

Turns out these sourcemap files are json. But no one uses a .json file extension, which seems unfortunate as the browser doesn't understand them, if you happen to try loading one of the files there. Not sure if there's a restriction about naming them, but it seems like there shouldn't be, and it seems like it makes sense to just use a .json extension for them.

embed the original source in the sourcemap file

Source map files contain a list of the names of the original source files (urls, actually), and can optionally contain the original source file content in the sourcesContent key. Not everyone does this - I think most people do not put the original source in the sourcemap files (eg, jquery, angular).

If you don't include the source with the sourcesContent key, then the source will need to be retrieved by your browser. Not only is this another HTTP GET required, but you will need to provide the original .js files as well as the minized .js files on your server. And they will need to be arranged in whatever manner the source files are specified in the source map file (remember, the names are actually URLs).

If you're going to provide a separate map file, then you might as well add the source to it, so the whole wad is available in one file.

generate your sourcemap json file so that it's readable

I'm looking at you, http://code.jquery.com/jquery-2.0.3.min.map.

The file is only used at debug time, it's unlikely there's going to be much of a performance/memory hit by single-lining the file. Remember, as I said above, it's often useful to be able to read the sourcemap file, so ... make it readable.

if you use the names key in your sourcemap, put it at the end of the map file

Again, sourcemap files are interesting reading sometimes, but the names key ends up being painful to deal with, if you generate the sourcemap with something like JSON.stringify(mapObject, null, 4) or something. Because the value of the names key is an array of strings, and it's pretty long, as is not nearly as interesting to read as the other bits in the source map. Add the property to your map object last, before you stringify it, so it doesn't get in the way.

where can we publish some sourcemap best practices?

I'd like to see somewhere we can publish and debate sourcemap best practices. Idears?

bugs opened

Some bugs relevant to the "sourceMappingURL not the last thing in the file" issue/violation:

Thursday, February 07, 2013

dustup

A few months ago, I took a look at Nathan Marz's Storm project. As someone who has used and implemented Actor-like systems a few times over the years, always fun to see another take. Although Storm is aimed at the "cloud", it's easy to look at it and see how you might be able to use it for local computation. In fact, I have a problem area I'm working in right now where something like Storm might be useful, but I just need it to work in a single process. In JavaScript.

Another recent problem area I've been looking at is async, and using Promises to help with that mess. I've been looking at Kris Kowal's q specifically. It's a nice package, and there's a lot to love. But as I was thinking about how I was going to end up using them, I imagined building up these chained promises over and over again for some of my processing. As live objects. Which, on the face of it, is insane. If I can build a static structure and have object flow through them instead. Should be able to cut down on the amount of live objects created, and it will probably be easier to debug.

So, with that in mind, I finally sat down and reinterpreted Storm this evening, with my dustup project.

Some differences from Storm, besides the super obvious ones (JavaScript vs Java/Clojure, and local vs distributed):

  • One of the things that didn't seem right to me in Storm was differentiating spouts from bolts. So I only have bolts.

  • I'm also a fan of the PureData real-time graphical programming environment, and so borrowed some ideas from there. Namely, that bolts should have inlets where data comes in, and outlets where they go out, and that to hook bolts together, that you'll connect an inlet to an outlet.

  • Designed with CoffeeScript in mind. So you can do nice looking things like this:

    x = new Bolt
        outlets:
           stdout: "standard output"
           stderr: "standard error"
    

    which generates the following JavaScript:

    x = new Bolt({
        outlets: {
           stdout: "standard output",
           stderr: "standard error"
        }
    })
    

    and this:

    Bolt.connect a: boltA, b: boltB
    

    which generates the following JavaScript

    Bolt.connect({a: boltA, b: boltB})
    

    Even though I designed it for and with CoffeeScript, you can of course use it in JavaScript, and it seems totally survivable.

Stopping there left me with something that seems useful, and still small. I hope to play with it in anger over the next week or so.

Here's an example of a topology that just passes data from one bolt to another, in CoffeeScript:
(here's the JavaScript for you CoffeeScript haters)

In the lines 1-2, we get access to the dustup package and the Bolt class that it exports.

On lines 4-6, we're creating a new bolt that only has a single outlet, named "a" (the string value associated with the property a - "outlet a" - is ignored).

On lines 8-11, we're creating a new bolt that only has a single inlet, named "b". Inlets need to provide a function which will be invoked when the inlet receives data from an outlet. In this case, the inlet function will write the data to "the console".

On line 13, we connect the a outlet from the first bolt to the b inlet of the second bolt. So that when we send a message out the a outlet, the b inlet will receive it.

Which we test on line 15, by having the first bolt emit some data. Guess what happens.

next

The next obvious thing to look at, is to see how asynchronous functions, timers, and intervals fit into this scheme.

Friday, November 30, 2012

weinre installable at heroku (and behind other proxy servers)

I finally resolved an issue with weinre relating to using it behind proxy servers.

Matti Paksula figured out what the problem was, but I wasn't happy with the additional complexity involved, so I made a simpler and more drastic change (in the getChannel() function).

Used to be, subsequent weinre connections after the first were checked to make sure they came from the same "computer"; that was just a silly sort of security check that can be worked around, if need be. So why bother with it, if it just gets in the way.

So, now weinre can run on heroku. I have a wrapper project at GitHub you can use to create your own server: https://github.com/pmuellr/weinre-heroku

Since Heroku provides 750 free dyno-hours per app per month, and weinre is one app, and uses one dyno at a time, and 750 hours are in a month, you can run a weinre server on the Intertubes for free.

As usual, weinre has been updated on npm.

Friday, March 30, 2012

unofficial weinre binary packages for your convenience at my apache home page

weinre is now getting ready to go for the brass ring at Apache: an "official" release.

NOT THERE YET - NO OFFICIAL RELEASES YET.

Until that time, I have unofficial binary packages available for your convenience.

I've gone ahead and created a little download site at my personal Apache page, here: http://people.apache.org/~pmuellr/.

The download site contains all the doc and binary packages for every weinre version I've 'shipped', in the 1.x directories. It also contains unofficial binary packages of recent cuts of weinre for your convenience, as the bin, doc, and src directories in the weinre-builds directory, and the same version of the doc, unpacked, in the latest directory of weinre-docs.

As with previous binary releases for your convenience, you can npm install weinre. Here's the recipe:

npm install {base-url}apache-cordova-weinre-{version}-bin.tar.gz

{base-url} = http://people.apache.org/~pmuellr/weinre-builds/bin/
{version}  = 2.0.0-pre-H0FABA3W-incubating

That version number will change, so I'm not providing an exact link. Check the directory.

help me help you

If you'd like to accelerate the process of getting weinre to "official" status, you can help!

  • install it
  • use it
  • review it
  • build it
  • enhance it

Feel free to post to the cordova mailing list at Apache, the weinre google group, clone the source from Apache or GitHub, etc. All the links are here: http://people.apache.org/~pmuellr/weinre-docs/latest/.

One link I forgot to add, and feel free to open a bug about this, is the link to open a bug. It's hideous (the URL). Add component "weinre" and maybe a "[weinre]" prefix on the summary.

Thank you for helping yourself!

you f'ing moved the downloads again you f'er!

Chill. And some bad news. The official releases won't be here (I don't think). But I will provide a link on that site to the official releases, when they become real.

I intend to keep this page around until I can get all the weinre bits available in more appropriate places at Apache. Not there yet.

personal home pages at Apache

Apache provides "home pages" for Apache committers. That's what I'm using for this archive site. If you're a committer, and curious about how I did the directory indexing, the source for the site (modulo actual archives), is here: https://github.com/pmuellr/people.apache.org.

2012/03/30 1pm update

Jan Lehnardt pointed out to me on twitter that I should avoid the use of the world "release", so that word has been changed to things like "binary package for your convenience".

Friday, February 17, 2012

npm installable version of weinre

As part of the port of weinre from Java to node.js it seemed logical to make it, somehow, npm installable.

Success.

There is currently a tar.gz download of the weinre runtime available at the pmuellr/incubator-cordova-weinre downloads page. I may keep a 'recent' build here until I get the continuous builds of weinre at Apache working. At which point, the tar.gz should be available somewhere at apache.

Of course, let me know if you have any issues. Preferred place for discussion is the weinre Google Group.

install locally

npm install https://github.com/downloads/pmuellr/incubator-cordova-weinre/weinre-node-1.7.0-pre-2012-02-17--16-47-15.tar.gz

After that install, you can run weinre via

./node_modules/.bin/weinre

install globally

sudo npm -g install https://github.com/downloads/pmuellr/incubator-cordova-weinre/weinre-node-1.7.0-pre-2012-02-17--16-47-15.tar.gz

After that install, you can run weinre via

weinre

notes/caveats

  • The command-line options have not changed, although the --reuseAddr option is no longer supported.

  • There is no longer a Mac 'app' version of weinre.

  • This is not an 'official build' of weinre, in the Apache sense. I need to figure out what that even means first.

  • These 'unofficial' builds have a horrendous semver patch version names. Deal. If you have a better scheme, please let me know.

  • I don't have plans to ever put weinre up at npmjs.org, since I have no idea how this would work, in practice. I don't want to own the weinre package up there; ideally it would be owned by Apache. Can't see how that would work either. If I ever do put a weinre package up at npm, I think it would be a placeholder with instructions on how to get it from Apache. Or maybe there's a way we can auto-link the npmjs.org package to Apache mirrors somehow?

  • I need to look at whether I should continue to ship all my package's pre-reqs (and their pre-reqs, recursively) or not. And relatedly, whether I should actually make fixed version pre-reqs of all the recursively pre-req'd modules. An issue came up today that I "refreshed" the node_modules, and got an unexpected update to the formidable package (a pre-req of connect which is a pre-req of express which is a pre-req of weinre). That's not great. And could be fixed by having explicit versioned dependencies of all the recursively pre-req'd modules in weinre itself. Sigh. What do other people do here?

  • Prolly need to improve the user docs. The remainder of this blog post is the shipped README.md file. So, to read the docs, start the server, read the docs the server embeds, online. Sorry.

running

For more information about running weinre, you can start the server and browse the documentation online.

Start the server with the following command

node weinre

This will start the server, and display a message with the URL to the server. Browse to that URL in your web browser, and then click on 'documentation' link, which will display weinre's online documentation. From there click on the 'Running' page to get more information about running weinre.


Update: Patrick Kettner posted a link to this blog post on Hacker News, so you can discuss there, since I'm one of those "disable comments on blog" people. http://news.ycombinator.com/item?id=3604291.